Actuarial

There are many different types of testing associated with software development and the development of calculations for financial models. Unit testing, functional testing, regression testing, integration testing and performance testing are some of the most common. Testing should always be carried out before a new version is deployed to users.

Unit testing involves testing individual units of a financial model in isolation. In the case of Mo.net models, these units would usually be individual functions. Unit tests verify that each function produces the expected results for a defined set of inputs.

This is particularly useful when developing or modifying models, as unit tests can help identify calculation errors early and provide confidence that existing functionality continues to behave as expected after changes are made.

Prior to Mo.net 7.8, functionality was already available for creating unit tests in the External Component area. Mo.net 7.8 now also includes functionality that makes it easy to write and execute unit tests for any function you wish to test.

Creating a unit test

I will run through an example using a function that is already present in one of our sample projects. The project is ConventionalModelProject, which can be found in the backstage area under New and Installed.

The top model, Disc_CF_Model contains a function that calculates the policy year. We are going to write a unit test to check the boundary points-in particular, when the policy year should change from 1 to 2.

The code for the Pol_Year function looks like this:

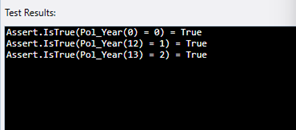
This means that when t = 0, Pol_Year is equal to 0. From t = 1 to t = 12, Pol_Year should equal 1, and from t = 13 to t = 24, it should equal 2.

Boundary testing

When writing unit tests, it is particularly useful to test values at and around boundaries where the expected result changes. Errors are often more likely to occur at these transition points-for example, because of an incorrect comparison operator or an off-by-one error.

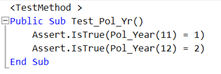
In this example, the important boundary is between t = 12 and t = 13, where Pol_Year changes from 1 to 2. Testing values on either side of this boundary confirms that t = 12 is still assigned to policy year 1 and that t = 13 is correctly assigned to policy year 2. It is also useful to test other boundaries, such as t = 0 and t = 1, rather than testing only values in the middle of a range.

Thinking about boundaries in this way can help when creating unit tests for other model functions. Wherever a calculation changes behaviour at a particular value, consider testing the value immediately before the boundary, the boundary itself and the value immediately after it.

We add a new function called Pol_Year_UT. To check that the boundary values are calculated correctly, we use the following code:
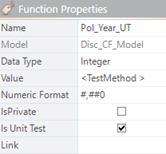
We also need to ensure that the Is Unit Test function property is selected:
Running the unit test

We can now run our unit test by clicking the Run Test button on the Function menu bar:

The results are displayed in the box below the code:
Running multiple unit tests

If a project contains multiple unit tests, they can all be run from the command line. To do this, use the /rununittests switch with the Model Development Studio executable and point it to the project for which you want to run the unit tests.

The results are then sent to the console, as shown below:
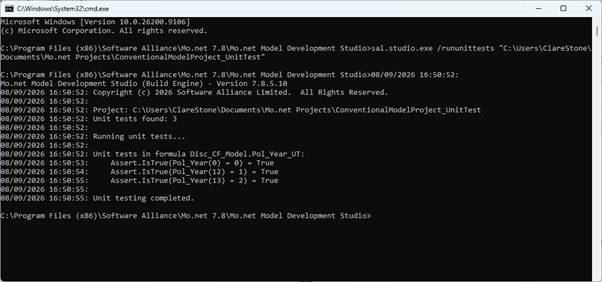
This provides a convenient way to run a project’s unit tests together, helping to confirm that calculations continue to produce the expected results as the model is developed and changed.

Conculsion

Unit testing provides a simple but effective way to check that individual model functions are producing the expected results. By creating tests as functions are developed, and focusing particularly on boundary conditions and other key calculation points, potential issues can be identified early and changes can be made with greater confidence. The unit testing functionality in Mo.net 7.8 makes it easier to incorporate these checks into the model development process and to rerun them whenever a model is changed.
Read more

As actuarial models continue to grow in complexity, the volume of data they process has increased dramatically. Whether you’re building pricing models, performing reserving analyses, running capital calculations or producing IFRS 17 results, the efficiency of your data layer has become just as important as the modelling logic itself.

For many years, CSV files have been the default way of exchanging data between systems. They’re simple, universally supported and easy to inspect with a spreadsheet or text editor. However, as datasets have grown into the millions of records, the limitations of CSV have become increasingly apparent.

That’s where Apache Parquet comes in.

Now natively supported in Mo.net (from 7.8 onwards), Parquet is a modern file format designed specifically for analytical workloads. It enables actuarial models to read data more efficiently, consume less storage and integrate seamlessly with today’s wider analytics ecosystem.

What is a Parquet File?

Unlike a CSV file, a Parquet file isn’t designed to be read by people. It’s a binary format, so opening one in a text editor simply produces unreadable characters. Instead, Parquet is designed for software.

The easiest way to understand the difference is to compare how the same data is stored.

A CSV file stores information row by row:

PolicyIDAgePremiumClaims
100142425.501
100235310.250
100357689.102
100429275.000

Internally, a Parquet file stores the same information more like this:

Schema
 ├─ PolicyID: Integer
 ├─ Age: Integer
 ├─ Premium: Double
 └─ Claims: Integer

PolicyID
1001
1002
1003
1004

Age
42
35
57
29

Premium
425.50
310.25
689.10
275.00

Claims
1
0
2
0

This isn’t the actual binary structure, but it illustrates the key concept: Parquet stores data by column rather than by row.

That difference unlocks many of the performance benefits that make Parquet so attractive for actuarial modelling.

Faster Model Execution

Consider a pricing model that only requires three variables:

  • Premium
  • Claim Count
  • Exposure

A traditional CSV file might contain dozens or even hundreds of columns:

PolicyIDAgeVehicleRegionPremiumClaim CountExposureOccupation

When Mo.net reads a CSV, every column has to be loaded from disk before the unwanted ones can be discarded.

With Parquet, Mo.net can read only the columns it needs.

Instead of loading the entire file, it simply retrieves:

  • Premium
  • Claim Count
  • Exposure

while skipping everything else.

For small datasets the difference may be negligible. For experience files containing millions of policies, the reduction in disk I/O can significantly improve loading and execution times.

Smaller Files, Lower Storage Costs

Another major advantage of Parquet is file size. The format includes highly efficient compression and encoding techniques, meaning Parquet files are often 50–90% smaller than equivalent CSV files, depending on the characteristics of the data.

For actuarial teams storing years of policy history, claims experience, assumptions and model outputs, these savings can quickly become substantial.

Smaller files also mean:

  • Faster backups
  • Faster transfers between systems
  • Lower cloud storage costs
  • Quicker loading into analytical platforms

Better Data Quality Through Strong Typing

CSV files only contain text. Every application importing a CSV has to decide whether each column represents a number, date or piece of text. Regional settings, missing values and formatting differences can all introduce unexpected issues.

Parquet stores the data type alongside the data itself.

  • Dates remain dates.
  • Numbers remain numbers.
  • Boolean values remain Boolean.

This reduces import errors and removes much of the repetitive data cleaning that often accompanies actuarial workflows.

Built for Large-Scale Analytics

Parquet has become the standard storage format across modern analytics platforms, including Python, R, DuckDB, Spark, Databricks, Microsoft Fabric and many cloud data warehouses. Because Mo.net supports Parquet directly, the same dataset can be shared across multiple analytical tools without exporting separate copies in different formats. This creates a single, consistent source of data across pricing, reserving, capital modelling and reporting teams.

Handling Large Experience Files Efficiently

Many actuarial investigations involve datasets containing tens or hundreds of millions of records. Parquet includes several features specifically designed for these workloads:

  • Columnar storage minimises unnecessary reads.
  • Built-in compression reduces storage requirements.
  • Rich metadata allows software to skip irrelevant sections of a file.
  • Partitioning makes it easy to work with individual years, products or business units.

Together, these capabilities allow Mo.net to process large datasets far more efficiently than traditional text-based formats.

A Better Foundation for Automated Data Pipelines

Modern actuarial modelling increasingly forms part of automated production processes. Data flows from operational systems into data lakes, through validation pipelines, into actuarial models and finally into reporting platforms.

Parquet fits naturally within these workflows because it preserves both data structure and data types. The result is more reliable automated processes, fewer manual interventions and reduced risk of data formatting issues disrupting production runs.

Why It Matters for Mo.net Users

Support for Parquet within Mo.net allows actuarial teams to benefit from industry-standard data technology without changing the way they build models.

Users can take advantage of:

  • Faster data loading
  • Reduced model execution times
  • Smaller data files
  • Lower memory consumption
  • More reliable handling of data types
  • Better integration with modern analytics platforms
  • Improved scalability as datasets continue to grow

These benefits apply across pricing, reserving, capital modelling, IFRS 17 and experience investigations.

Looking Ahead

The actuarial profession is rapidly embracing larger datasets, cloud-native architectures and increasingly sophisticated analytical techniques. Parquet has emerged as one of the foundational technologies enabling that transition.

By supporting Parquet, Mo.net gives actuarial teams access to a faster, more scalable and more robust way of managing model data. Rather than treating data loading as a bottleneck, modellers can focus on what matters most—developing better models and delivering insights more quickly.

For organisations looking to modernise their actuarial workflows, adopting Parquet isn’t simply a technical upgrade. It’s an investment in a data platform that’s designed for the future.

Read more

y 2035, no one in life insurance still talks about “running the model”.

That phrase belongs to an earlier era; a time when modelling was an event rather than a capability, when results arrived hours or days after questions were asked, and when insight lagged behind decision-making.

In 2035, modelling is simply there. Always on. Always available. And quietly shaping almost every material decision a life insurer makes.

Read more

Every few years, life insurance modelling circles back to a familiar idea: “Surely we can build this ourselves now?”

Open-source languages are mature. Cloud infrastructure is cheap and elastic. Numerical libraries are faster than ever. On the surface, the case for fully open-source financial modelling feels stronger than it ever has.

And yet, time and again, large-scale internal build attempts quietly stall, get re-scoped, or end up re-introducing vendor platforms through the back door. This isn’t because open source has failed actuarial modelling. It’s because life insurance modelling turns out to be much more than code.

Read more

Over the last decade a number of free / open source database environments such as PostgreSQL and MySQL have emerged to challenge the traditional players like Microsoft SQL Server and Oracle.  Like PostgreSQL and MySQL, SQLite has found favour with lone developers using limited data sets or developing lightweight applications.  Even users of SQL Server Express Edition have moved to SQLite, where compatibility with the full edition of SQL Server isn’t a significant requirement.

Read more

The U.S. insurance industry is undergoing a major shift in how it calculates statutory reserves for fixed annuity products. Leading this transformation is VM-22, a new reserving standard that officially became mandatory in 2025 for many non-variable annuities. With its adoption, insurers are moving away from traditional formula-based methods and embracing a more nuanced, principle-based approach—one that better reflects the complexity and risks of modern annuity products.

Read more